Measuring the accuracy of an AI agent for short-term rentals: 380 questions, zero wrong answers
A study of Santi, the AI agent in Santara AI: 19 operational questions asked 20 times each on a live portfolio and scored against the dashboard. 0 of 380 answers were wrong; 377 were complete and correct (99.2%); median answer time 6.4 s.
 Tai Pham
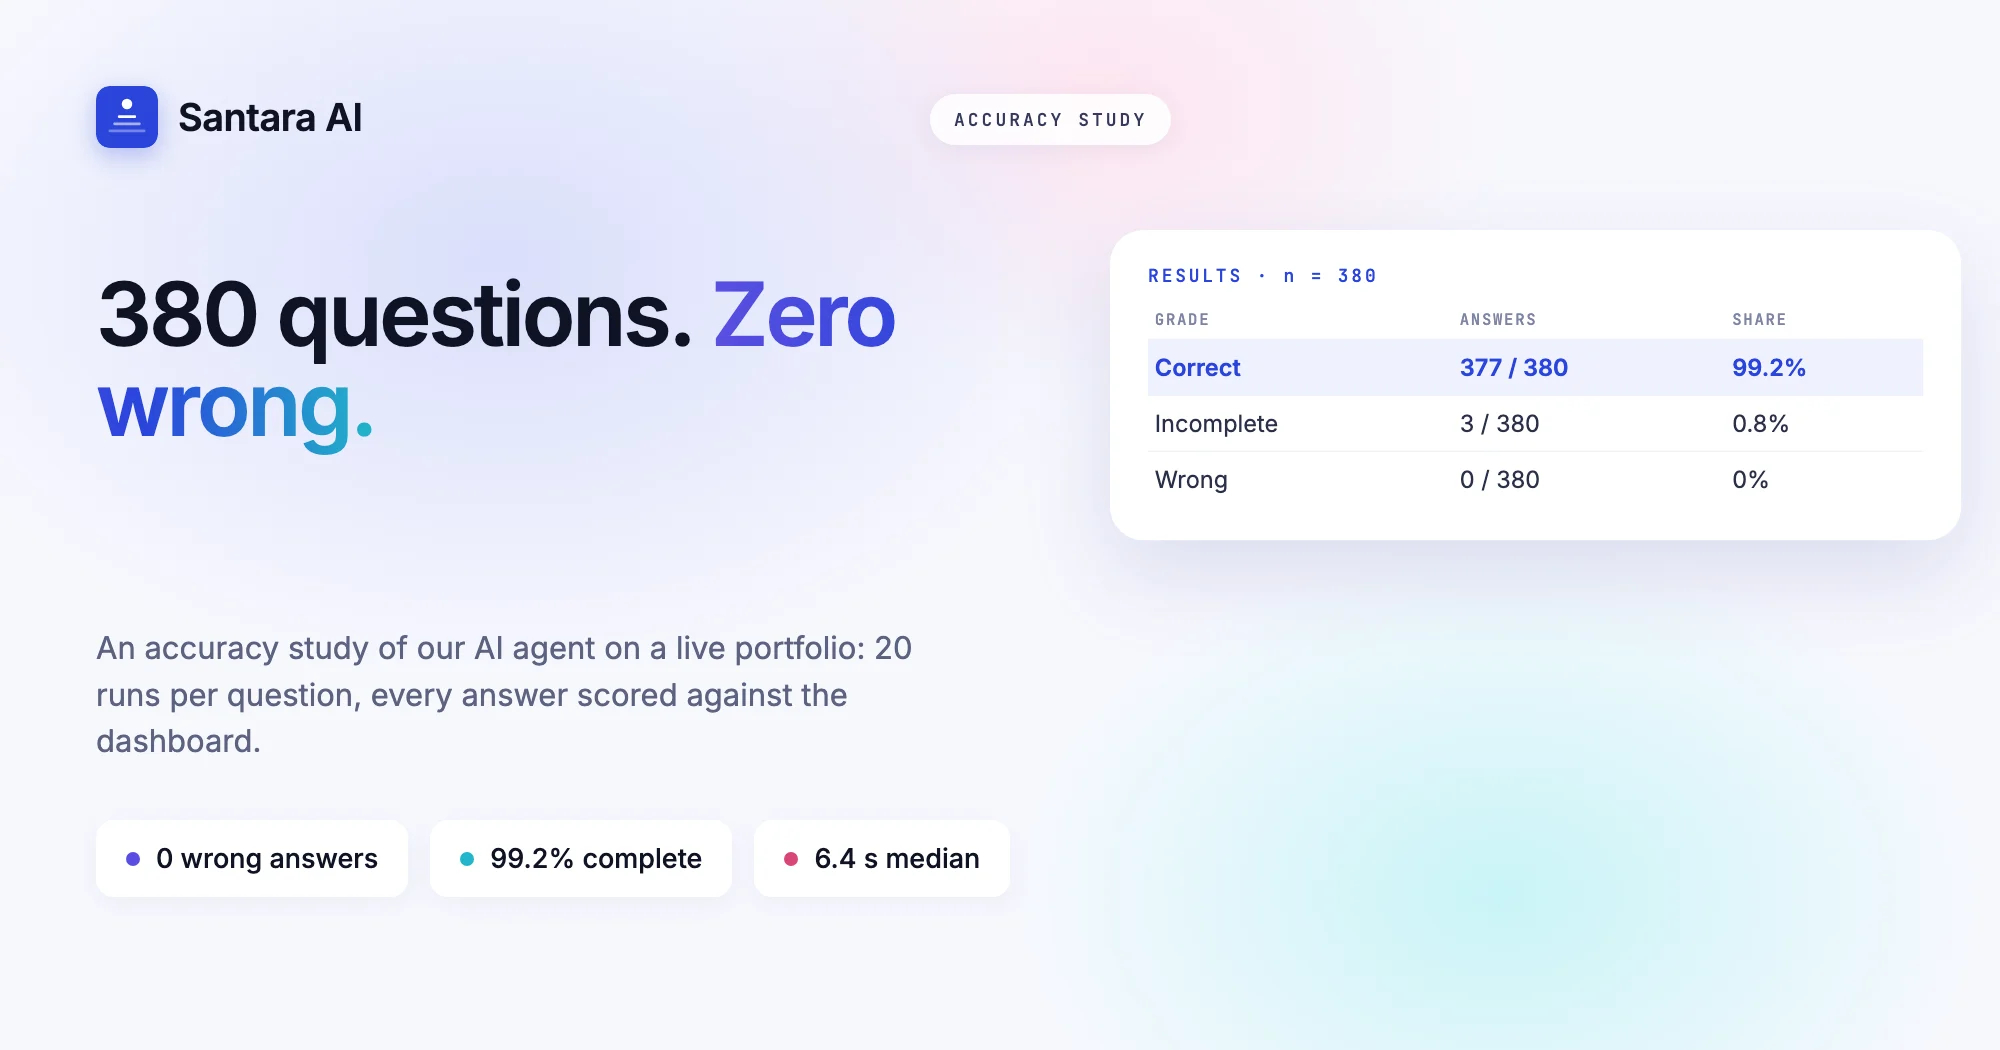
Abstract. We measured the factual accuracy of Santi, the AI agent in Santara AI, on a live short-term-rental portfolio. Nineteen operational questions were each asked 20 times (n = 380) through the production service, with the conversation cleared after every answer, and every answer was scored against the figures in the Santara AI dashboard. No answer contained a wrong figure (0 of 380; 95% CI 0.0–1.0%). 377 answers were complete and correct (99.2%; 95% CI 97.7–99.7%) and 3 were incomplete (0.8%). Median time to a complete answer was 6.4 s (IQR 5.4–8.3 s). We describe the method, report results per question, analyse the three incomplete answers, and report the changes made after the study.
1. Introduction
An AI agent that operates a rental business is useful only if its figures can be trusted: "14 arrivals next week" decides who cleans, who greets and how empty nights are priced. Product demonstrations show answers a system gets right; they do not show how often it gets them right. This study measures that rate directly, on real operating data, with the system's own dashboard as the reference.
2. Method
2.1 System under test
Santi is the AI agent built into Santara AI. It answers questions by reading the host's bookings, inbox, reviews, revenue and owner statements through read-only tools, and any change it proposes requires the host's confirmation twice. Each answer that reads data ends with a sources line: when the data was read and a link to the Santara AI screen it came from. The production service was tested as deployed on 13 October 2026.
2.2 Data
A single operating portfolio of 12 short-term-rental listings in Southeast Asia, at 92% occupancy on the test day. To protect the owner and guests, the portfolio and guest names are not disclosed, and monetary results are reported only as matched or not matched.
2.3 Questions
Nineteen questions in four categories (Appendix A): counts (bookings, nights, occupancy, turnovers, inbox, reviews; 10 questions), guest names (arrivals and departures; 4), money (revenue, nightly rate, owner statement; 3), and other languages (the check-in question in Vietnamese and Indonesian; 2). All questions were read-only.
2.4 Procedure
Each question was asked 20 times, in 20 rotating rounds of all 19 questions, through the same streaming endpoint the Santi app uses, signed in as the host. The conversation history was cleared after every answer, so no answer could depend on an earlier one. After the 380 automated runs, all 19 questions were also typed once into the live chat page in a browser.
2.5 Reference values and scoring
Reference values were read from Santara AI at the start of the run: the calendar, the inbox counts, the Reviews page totals, the owner statement and the Daily Brief. Each answer was graded on a three-level scale:
- Correct: states the reference figure (money within 1%) or names every guest, in the language asked.
- Incomplete: contains no wrong figure, but omits part of what was asked.
- Wrong: states a figure or name that contradicts the reference.
Grading was automatic text matching; every answer not graded correct was then read by hand.
2.6 Statistics
Proportions are reported with 95% Wilson score intervals, which remain valid at small samples and at 0% or 100%. Response time is the wall-clock time from sending the question to the end of the answer, reported as median and interquartile range (IQR).
3. Results
3.1 Accuracy
No answer was wrong. Sixteen of the 19 questions were answered correctly in all 20 runs; the other three in 19 of 20 (Figure 1).
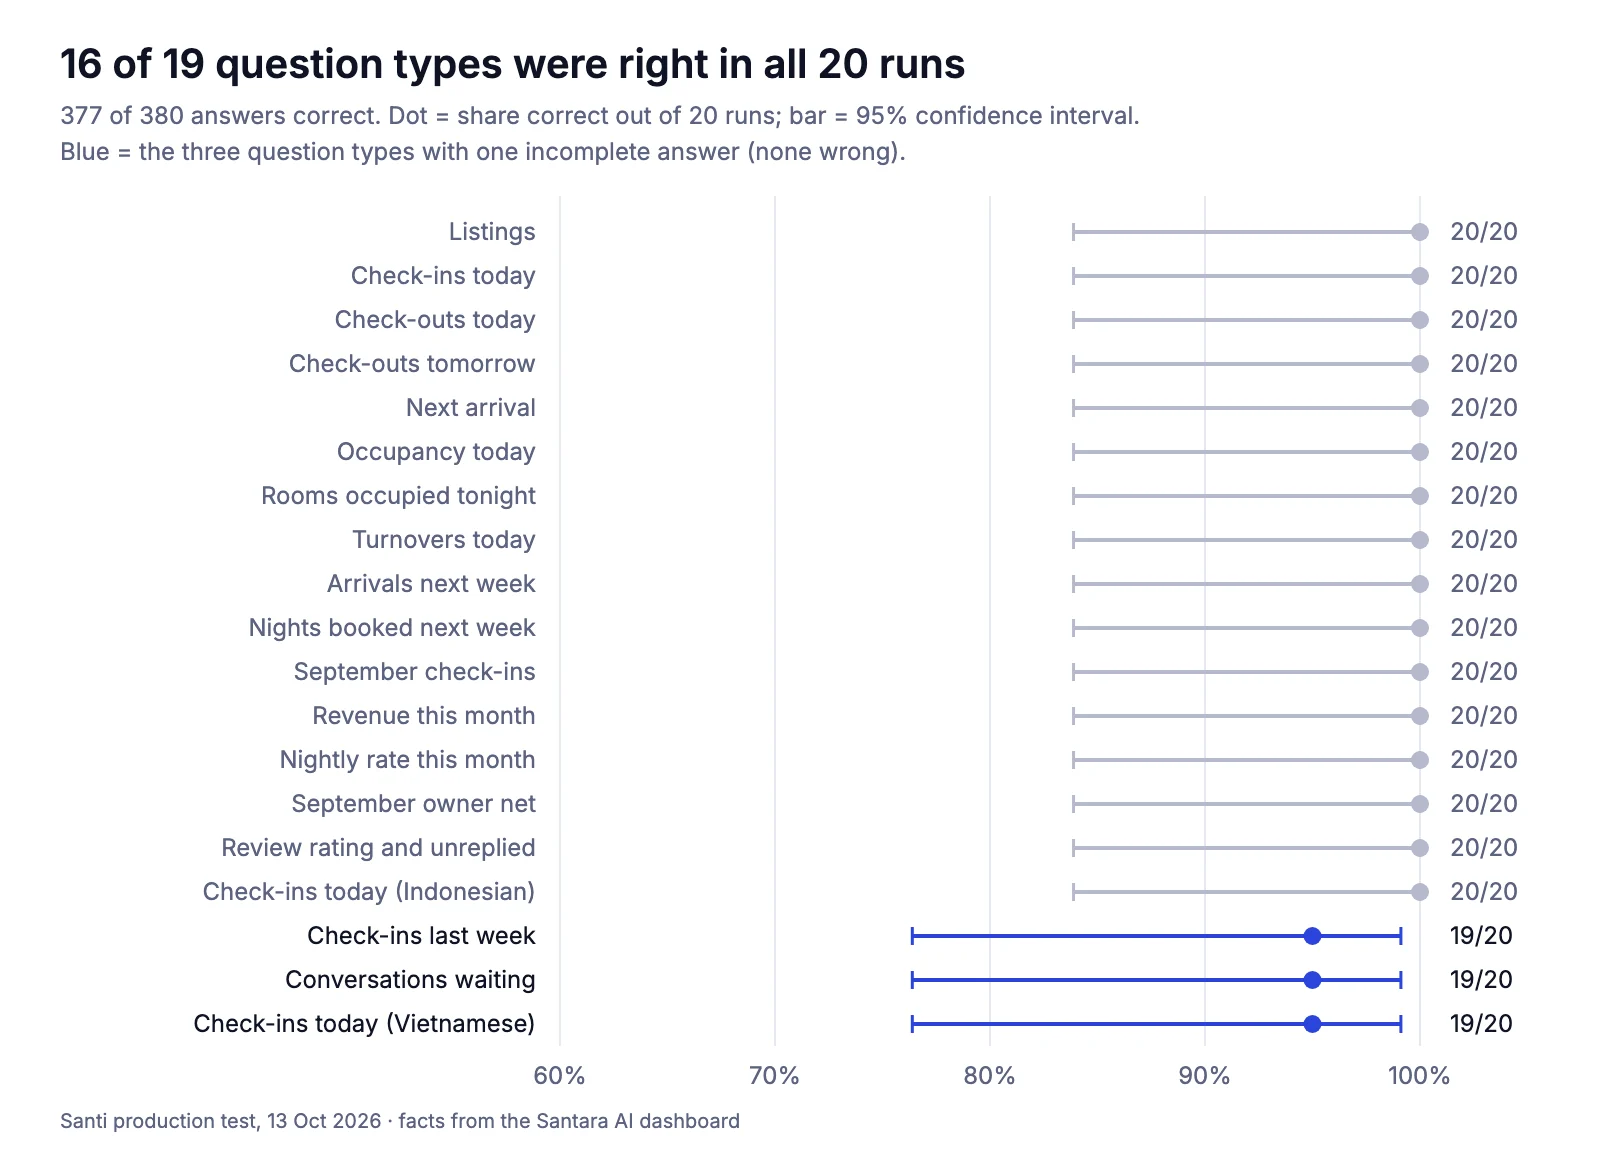
Table 1. Results by category (n = 380).
| Category | Questions | Correct | Incomplete | Wrong |
| Counts | 10 | 198 / 200 | 2 | 0 |
| Guest names | 4 | 80 / 80 | 0 | 0 |
| Money | 3 | 60 / 60 | 0 | 0 |
| Other languages | 2 | 39 / 40 | 1 | 0 |
| All | 19 | 377 / 380 (99.2%; CI 97.7–99.7%) | 3 (0.8%) | 0 (CI 0.0–1.0%) |
All money answers matched the dashboard, including the owner statement, which nets channel fees and expenses from gross revenue and assigns each stay to its check-out month. The browser pass through the live chat page gave the same outcome: 19 of 19 correct.
3.2 Response time
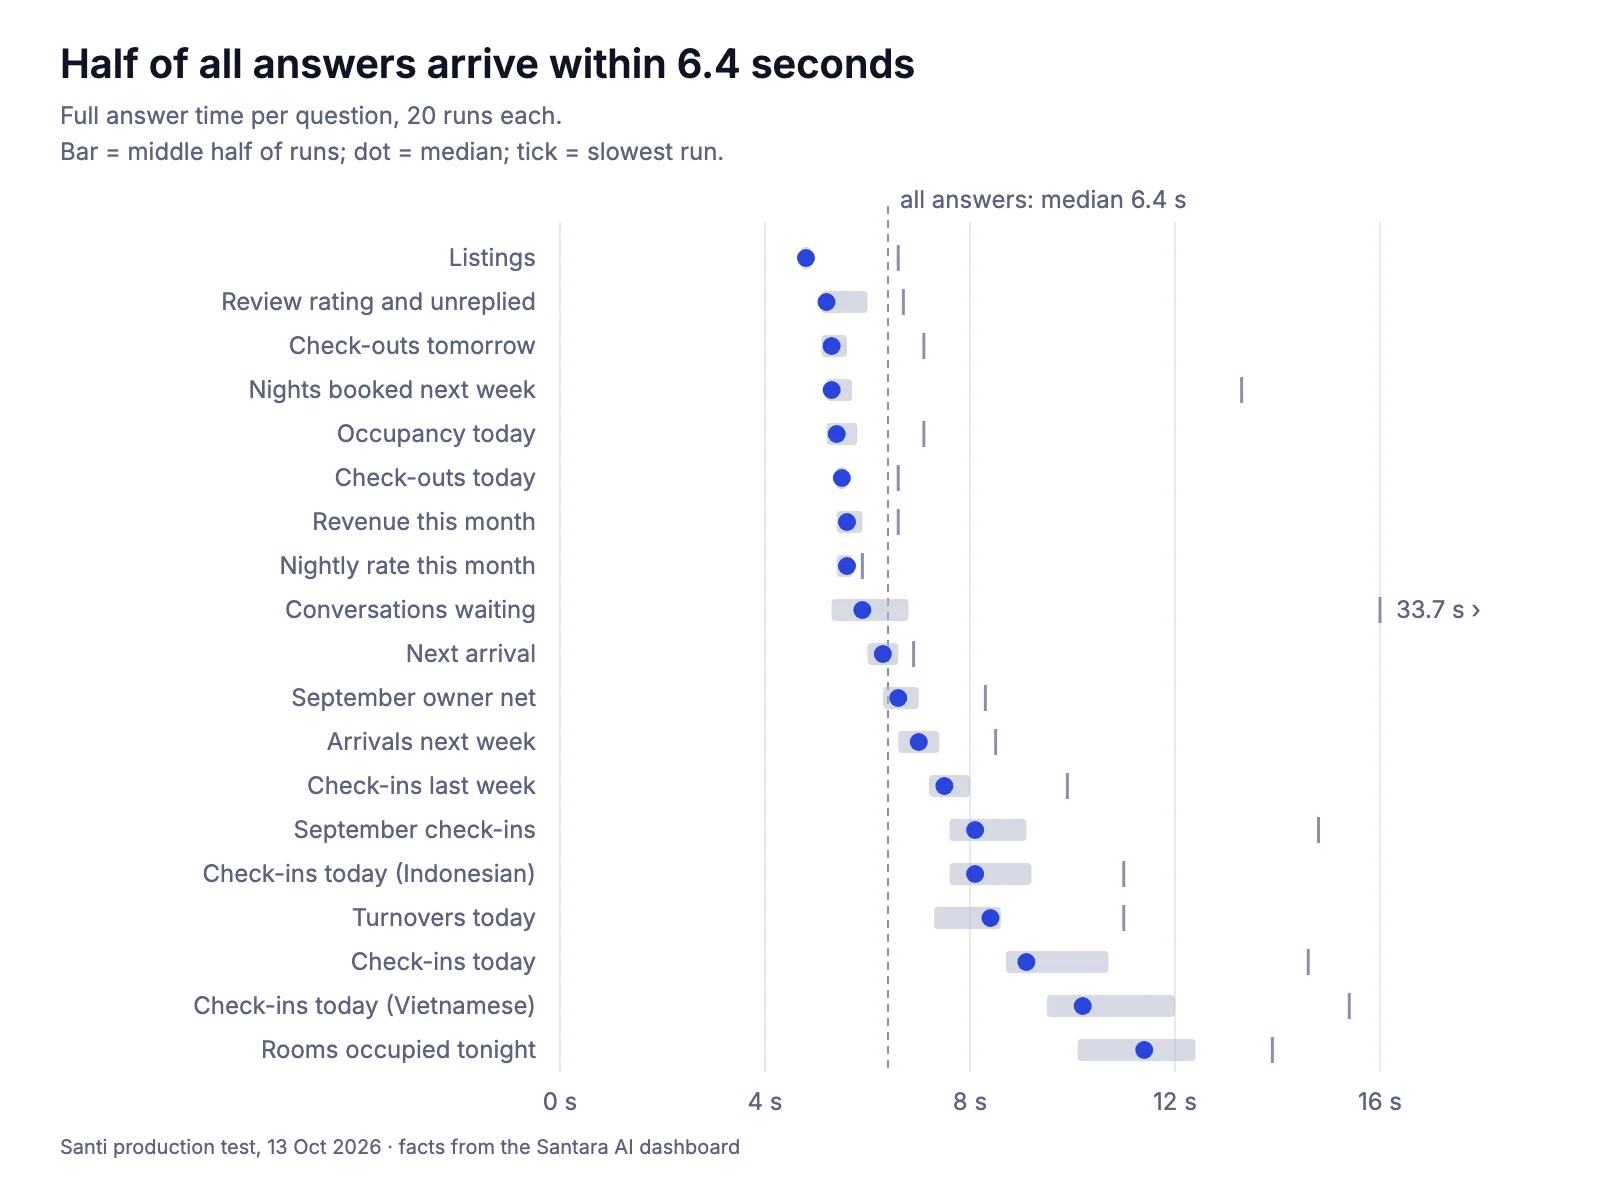
The median time to a complete answer was 6.4 s (IQR 5.4–8.3 s; 95th percentile 12.0 s; maximum 33.7 s, one run). The first words appeared after a median of 4.5 s. Single look-ups took about 5 s; questions that combine several sources, such as rooms occupied tonight, took about 10 s (Figure 2).
3.3 Supporting signals
Table 2. Signals that let a host verify an answer.
| Signal | Result |
| Answers with a sources line (time read + link) | 379 / 380 |
| Weekday stated correctly for the date | 379 / 380 |
| Answered in the language asked | 40 / 40 |
| Grounding warnings shown | 22, all on correct figures |
Santi flags any figure in its answer that does not appear in the data it read. All 22 flags fell on figures it had derived correctly rather than read: the sum of a month's expense lines (20 runs) and a net-of-fees nightly rate (2 runs). The check therefore produced no misses and 22 false alarms in this study.
4. Error analysis
Each of the three incomplete answers had a distinct cause (Table 3).
Table 3. The three incomplete answers.
| Question | Run | What the host received | Cause |
| Guests who checked in last week | 8 of 20 | No reply; asking again returned the correct figure, 14 | The model ended its turn without writing after a correct look-up; no automatic retry existed |
| Conversations waiting for a reply | 17 of 20 | "12 this week, plus 29 older", without the total of 41 | The tool returned the count in two parts, and the agent is instructed never to add figures itself |
| Who checks in today (Vietnamese) | 11 of 20 | "3 guests check in today", with 2 of 3 named in the text | The arrivals list was on screen as a card, and the agent is instructed not to repeat a card; the host would have seen all three names |
One further answer, graded correct, opened with "18 guests checked in last week" before correcting itself to 14, because 4 of those bookings had been cancelled. The final figure was right, but the first sentence was misleading.
5. Discussion
The results support two claims. First, on this data the agent did not state wrong figures: across 380 answers, the upper bound of the 95% interval for wrong answers is 1.0%. Second, the remaining errors were omissions caused by the agent's own design rules, not by misreading data, which makes them directly fixable.
All three were fixed and released after the study:
- a turn that looks something up but writes nothing now asks once more for the answer;
- "how many are waiting" now states the total first, then the split;
- direct questions (who, how many) are answered in full in words, even when a card shows the same list.
A re-test of the three affected questions plus one English control question (20 runs) returned 20 of 20 complete and correct answers. Two changes remain open: tools will return every total the agent needs, removing the 22 false alarms; and future tests will grade a misleading first sentence as incomplete.
6. Limitations
One portfolio, one day and one set of reference values; results may differ for larger or less active portfolios. Grading was automatic text matching with manual review of every non-correct answer. One reference value, the inbox count, changed during the run and was accepted within ±1. The post-fix re-test was smaller (20 runs) and ran on a separate test workspace.
7. Conclusion
Across 380 production answers on a live portfolio, Santi stated no wrong figure, answered 99.2% of questions completely and correctly, and returned a complete answer in a median of 6.4 seconds, each with a link to the screen it came from. The three incomplete answers have been fixed. We will repeat this study as Santi grows and publish the results.
You can ask Santi these questions about your own business: try Santi and compare its answers with your Santara AI dashboard.
Appendix A. Questions and results
Correct answers out of 20 runs, and median time to a complete answer.
| # | Question | Category | Correct | Median time |
| 1 | How many listings do I have? | Counts | 20 / 20 | 4.8 s |
| 2 | Who checks in today? | Names | 20 / 20 | 9.1 s |
| 3 | Who checks out today? | Names | 20 / 20 | 5.5 s |
| 4 | Who checks out tomorrow? | Names | 20 / 20 | 5.3 s |
| 5 | When is my next arrival after today, and who is it? | Names | 20 / 20 | 6.3 s |
| 6 | What is my occupancy today? | Counts | 20 / 20 | 5.4 s |
| 7 | How many of my rooms are occupied tonight? | Counts | 20 / 20 | 11.4 s |
| 8 | How many turnovers do I have today? | Counts | 20 / 20 | 8.4 s |
| 9 | How many arrivals do I have next week? | Counts | 20 / 20 | 7.0 s |
| 10 | How many nights are booked next week? | Counts | 20 / 20 | 5.3 s |
| 11 | How many guests checked in last week? | Counts | 19 / 20 | 7.5 s |
| 12 | How many bookings checked in during September? | Counts | 20 / 20 | 8.1 s |
| 13 | What is my revenue this month so far? | Money | 20 / 20 | 5.6 s |
| 14 | What is my average nightly rate this month so far? | Money | 20 / 20 | 5.6 s |
| 15 | What was my owner net for September? | Money | 20 / 20 | 6.6 s |
| 16 | How many guest conversations are waiting for my reply? | Counts | 19 / 20 | 5.9 s |
| 17 | What is my average review rating, and how many reviews haven't I replied to? | Counts | 20 / 20 | 5.2 s |
| 18 | Hôm nay ai nhận phòng? (Vietnamese: who checks in today?) | Languages | 19 / 20 | 10.2 s |
| 19 | Siapa yang check-in hari ini? (Indonesian: who checks in today?) | Languages | 20 / 20 | 8.1 s |